AI Agent Examples: 20 Real-World Enterprise Use Cases
AI agents attract attention for their autonomy, but the real business challenge is identifying where that autonomy produces useful, controllable work.
An AI agent is a system that can interpret a goal, select or plan actions, use tools, evaluate results and continue until it completes the task or requires human input.
It is what moves AI from answering questions to executing work. It is why organizations must evaluate agents as operational systems rather than more capable chatbots.
Real-world AI agents are being applied to customer support, software development, account research, invoice processing, employee services, logistics and scientific research. Most production deployments are not unrestricted digital employees. They operate within defined permissions, data sources, policies and approval thresholds.
Key Takeaways
- AI agents select and execute actions instead of only generating answers.
- Many products called agents are workflows with one agentic decision point.
- Customer support and software engineering are among the clearest current applications.
- Strong use cases have verifiable outputs, reliable data and reversible actions.
- Finance, HR and security agents require stricter permissions and human checkpoints.
- Success should be measured through completed work, errors, cost and policy compliance.
20 AI Agent Examples at a Glance
The evidence labels in this table distinguish publicly documented deployments from enterprise patterns and illustrative applications.
| # | AI agent example | Classification | Evidence status | Main human checkpoint |
| 1 | Customer-service resolution | Agent | Verified case | Policy exceptions |
| 2 | Support-ticket triage | Hybrid | Illustrative application | Ambiguous routing |
| 3 | Employee IT service desk | Hybrid | Illustrative application | Privileged changes |
| 4 | Enterprise knowledge retrieval | Agent | Verified case | Sensitive information |
| 5 | Sales-account research | Agent | Documented pattern | External outreach |
| 6 | Lead qualification | Hybrid | Illustrative application | Rejection or prioritization |
| 7 | Proposal and RFP preparation | Hybrid | Illustrative application | Commitments and pricing |
| 8 | Account management | Agent | Documented pattern | Customer communication |
| 9 | Marketing campaign operations | Hybrid | Documented pattern | Publication |
| 10 | Software engineering | Agent | Verified case | Code merge and release |
| 11 | Incident investigation | Agent | Illustrative application | Production remediation |
| 12 | Cybersecurity alert triage | Agent | Illustrative application | Containment |
| 13 | Invoice processing | Hybrid | Verified case | Payment approval |
| 14 | Expense management | Hybrid | Official illustration | Policy exceptions |
| 15 | Procurement support | Hybrid | Illustrative application | Supplier selection |
| 16 | Contract analysis | Hybrid | Illustrative application | Legal interpretation |
| 17 | Financial reconciliation | Hybrid | Illustrative application | Journal approval |
| 18 | Employee onboarding | Hybrid | Documented pattern | Access provisioning |
| 19 | Supply-chain exception management | Agent | Verified case | Rerouting and expenditure |
| 20 | Scientific research | Agent | Verified case | Scientific conclusions |
What Is an AI Agent?
An AI agent is an AI-enabled system that directs some of its own processes and tool use while pursuing a defined objective.
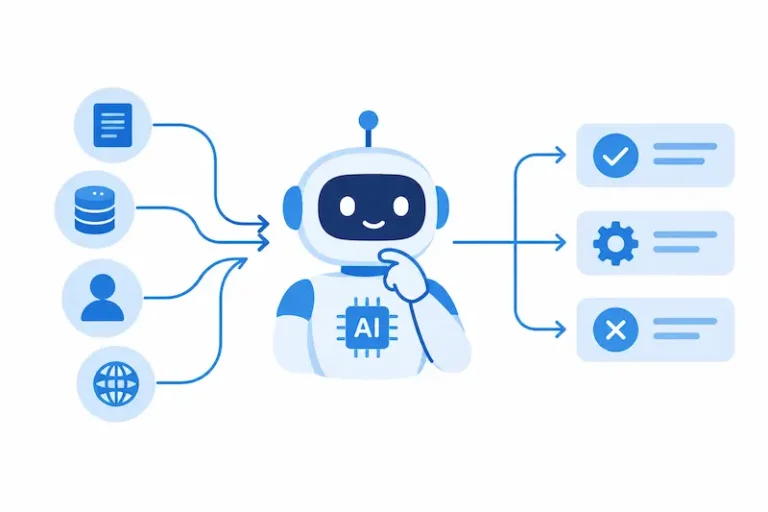
For example, a generative AI assistant might draft a customer email after receiving a prompt. An agent could retrieve the customer’s record, examine earlier correspondence, check the applicable policy, draft the response, request approval, send it and update the customer relationship management system.
Anthropic describes an agent as operating through a self-directed loop: it plans, acts, observes the result and adjusts until the task is finished or human input becomes necessary. Its explanation identifies four components that affect an agent’s capabilities and risks: the model, its instructions and guardrails, available tools, and the operating environment. This distinction is explained in Anthropic’s guidance on how trustworthy AI agents work.
A functional agent usually has five characteristics:
| Characteristic | Meaning |
| Goal | It receives an outcome to pursue |
| Planning | It selects or sequences actions |
| Tool use | It can retrieve, calculate, create or update |
| Feedback | It evaluates results and adjusts |
| Boundaries | Permissions and policies limit its authority |
AI Agent vs Chatbot, Copilot and Automation
The difference is not simply whether a system uses a large language model. It is about who determines the workflow and what the system is authorized to do.
| System | Primary function | Who determines the steps? | Typical autonomy |
| Chatbot | Answers questions | Human or predefined script | Low |
| Copilot | Assists a person performing work | Human | Low to moderate |
| Traditional automation | Executes fixed rules | Process designer | Low |
| Hybrid workflow | Combines fixed steps with agentic decisions | Designer and AI | Moderate |
| AI agent | Chooses actions while pursuing a goal | AI within defined boundaries | Moderate to high |
| Multi-agent system | Coordinates specialized agents | Orchestrator and agents | Variable |
A retrieval system that finds a policy and summarizes it is not necessarily an agent. A system that decides which sources to search, detects conflicting policies, asks for missing context and opens a review task has stronger agentic characteristics.
How to Tell Whether a System Is Really an Agent
A proposed system is more likely to qualify as an agent if it can answer yes to most of these questions:
- Does it select its next action based on what it observes?
- Can it choose among tools or information sources?
- Can it revise its approach after an unsuccessful attempt?
- Does it retain relevant context across multiple steps?
- Can it decide when to stop, continue or escalate?
A system that follows the same predetermined path every time is generally an automated workflow, even if a language model performs one of the steps.
Many useful enterprise systems are hybrids. They use fixed automation for predictable transactions and an agent only where interpretation, tool selection or exception handling is required. A hybrid is often safer and less expensive than making an entire process agentic.
Customer Service and Employee Support
1. Customer-Service Resolution Agent
A customer-service resolution agent interprets a request, retrieves account information, checks an approved policy and selects an appropriate action. It might reschedule a delivery, update contact information or report the status of a refund.
DoorDash developed a voice-operated self-service system for selected requests from consumers, merchants and delivery workers. Its published customer-service AI case study describes a system fielding hundreds of thousands of calls per day. This is a provider-reported result from one deployment, not a universal performance benchmark.
Verdict: Agent. The system interprets the request and uses connected tools to pursue a resolution.
Human checkpoint: Refund exceptions, disputed transactions and requests outside approved policy.
Best success measure: Correct resolution rate without repeat contact.
2. Support-Ticket Triage Agent
Ticket triage requires more than placing a message into a predefined category. An agentic version can inspect related service events, search previous incidents, request missing information and decide which specialist team should receive the case.
Most routing logic remains deterministic. Agentic reasoning is useful when the request is incomplete, spans several services or does not match an existing category.
Verdict: Hybrid. Rules can route predictable cases, while an agent investigates ambiguous ones.
Evidence status: Illustrative application. This describes a technically feasible workflow rather than a specific named deployment.
Human checkpoint: Security-sensitive, high-priority or repeatedly reassigned cases.
Best success measure: Correct first-assignment rate.
3. Employee IT Service-Desk Agent
An internal service agent can diagnose common software problems, search an approved knowledge base, run read-only checks and open or update a service ticket.
For example, it might identify a known application outage before guiding an employee through unnecessary troubleshooting. It could also collect device details and logs before escalating the case to an engineer.
The agent should not grant administrative privileges, disable security controls or install unapproved software independently.
Verdict: Hybrid. Diagnosis may be agentic, while identity checks and system changes should follow controlled workflows.
Evidence status: Illustrative application.
Human checkpoint: Privileged access, security-control changes and production-system actions.
Best success measure: Resolution rate for eligible requests without incorrect system changes.
4. Enterprise Knowledge Agent
A knowledge agent searches approved repositories, selects relevant sources and produces an answer with traceable citations. It may also identify conflicting documents, locate the responsible owner and initiate a content-review request.
Graebel has publicly described using agents for knowledge retrieval, invoice processing and action-based workflows across its business applications. The documented Graebel AI agent deployment demonstrates how agents can connect information across previously fragmented systems.
Verdict: Agent when the system chooses sources, resolves gaps and takes follow-up actions. Simple retrieval and summarization alone would be a retrieval workflow.
Human checkpoint: Conflicting policies, regulated guidance and restricted information.
Best success measure: Supported-answer accuracy, including citation correctness.
Sales and Marketing
5. Sales-Account Research Agent
Account research becomes agentic when the system determines what to investigate based on what it finds.
The agent might begin with a company profile, identify a recent expansion, search for the relevant business unit, compare the development with the seller’s qualification criteria and prepare a cited account brief. It can also check the customer relationship management system to avoid duplicating existing work.
OpenAI’s reporting on how enterprises use AI agents describes agents spreading into sales and other knowledge-work functions. It gives the example of combining company playbooks, customer information and previous proposals to prepare a tailored response for human review.
Verdict: Agent.
Human checkpoint: Any external outreach or sensitive inference.
Best success measure: Percentage of cited research findings accepted by account owners.
6. Lead-Qualification Agent
Many systems marketed as lead agents are actually fixed workflows. They enrich every lead, apply the same scoring criteria and route the record according to predetermined rules.
An agent is justified when the next research step depends on the information already gathered. For example, the system might investigate ownership, market activity or technical requirements differently for each prospect.
Verdict: Usually hybrid. Fixed qualification rules should remain deterministic, while unusual cases may require agentic research.
Evidence status: Illustrative application.
Human checkpoint: Disqualification, high-value prioritization and the use of inferred personal information.
Best success measure: Sales acceptance rate, monitored alongside incorrect disqualifications.
7. Proposal and RFP Agent
A proposal agent can interpret tender requirements, create a compliance matrix, search an approved response library and assemble a first draft.
The agentic element appears when the system identifies missing evidence, decides which repository to search and routes unanswered requirements to the appropriate specialist. It should clearly distinguish reusable approved statements from newly generated language.
Pricing, service-level commitments, legal representations and customer claims require accountable human approval.
Verdict: Hybrid. Requirement analysis can be agentic, while submission and approval follow fixed controls.
Evidence status: Illustrative application.
Human checkpoint: Pricing, contractual commitments and claims about capabilities or customers.
Best success measure: Percentage of requirements correctly mapped to supported responses.
8. Account-Management Agent
An account-management agent monitors approved signals such as unresolved cases, renewal dates, recorded commitments and documented usage trends.
It can prepare a meeting brief, identify open actions and suggest a follow-up plan. After a meeting, it might update the account record and assign approved internal tasks.
The system should separate factual customer records from its own interpretation. It should never represent an inferred risk or sentiment as something the customer explicitly said.
Enterprise usage data published in OpenAI’s assistance-to-execution report supports the broader adoption of agentic workflows in sales and account-related work.
Verdict: Agent when it chooses which signals to investigate and which actions to recommend.
Evidence status: Documented enterprise pattern.
Human checkpoint: Customer-facing messages, commercial decisions and contract changes.
Best success measure: Account-owner acceptance of identified actions.
9. Marketing Campaign Operations Agent
A marketing operations agent can research a topic, retrieve approved brand guidance, prepare content variants and adapt them for selected channels.
A more advanced system might coordinate specialized research, copy, design-brief and quality-review agents. Multiple agents are not automatically better. Every additional handoff creates another opportunity for factual drift, inconsistency and unnecessary cost.
OpenAI reports that enterprise agent use has expanded across marketing as well as sales, legal and recruiting. This demonstrates growing adoption of agentic tools in these functions, but it does not prove that every marketing task benefits from an agent.
Verdict: Hybrid. Research and adaptation may be agentic; publication should follow an approval workflow.
Human checkpoint: Factual claims, targeting, intellectual property and publication.
Best success measure: Approved outputs per cycle, adjusted for corrections and rework.
Software, Data and Cybersecurity
10. Software-Engineering Agent
A software-engineering agent can inspect a repository, interpret a development task, modify several files, run tests and revise its implementation when tests fail.
This is a strong AI agent use case because the environment produces rapid feedback. Code compiles or fails, tests pass or fail, and proposed changes can remain isolated until reviewed.
OpenAI’s enterprise report states that Virgin Atlantic used Codex to refactor legacy code. Other documented enterprise applications include generating tests, examining large repositories and fixing defects. These are provider-published examples, so organizations should evaluate performance in their own repositories and development environments.
Verdict: Agent. The system selects actions, edits files and responds to test results.
Human checkpoint: Code merge, security acceptance and production release.
Best success measure: Accepted changes that pass independent review and testing.
11. Incident-Investigation Agent
An incident-investigation agent can gather logs, deployment events, alerts and recent code changes to build a supported incident timeline.
Instead of following the same diagnostic checklist, it chooses the next query based on the evidence it discovers. If a recent deployment aligns with the start of an error spike, it can inspect that change before investigating unrelated infrastructure.
The output should show every material source, query and assumption. Engineers must be able to reconstruct how the agent reached its conclusion.
Verdict: Agent.
Evidence status: Illustrative application.
Human checkpoint: Rollbacks, configuration changes, database actions and customer communications.
Best success measure: Correctly supported incident hypotheses and reduced investigation time.
12. Cybersecurity Alert-Triage Agent
A security agent can correlate alerts, enrich indicators, inspect permitted logs and assemble an investigation record for an analyst.
Low-risk false positives may be closed under narrowly defined rules. Suspicious cases should be escalated with the evidence already collected. High-impact containment, such as disabling an account or isolating a critical production system, requires stricter authorization.
Agents introduce additional security exposure because they process untrusted content while holding access to tools. Anthropic’s guidance on trustworthy agent security warns that prompt injection can hide hostile instructions inside emails, documents or websites and that no single defense guarantees protection.
Verdict: Agent for adaptive investigation; hybrid when containment follows deterministic controls.
Evidence status: Illustrative application.
Human checkpoint: Destructive or business-disrupting containment.
Best success measure: Confirmed threats identified per analyst-review hour, alongside false-positive rates.
Finance, Procurement and Legal Operations
13. Invoice-Processing Agent
An invoice-processing system can extract invoice details, compare them with purchase orders and receipts, identify discrepancies and prepare an entry in the finance system.
Most successful implementations should remain hybrid. Deterministic rules handle exact matches, while an agent investigates unfamiliar descriptions, missing documents or inconsistent records.
Graebel has publicly documented the use of AI agents for invoice processing and connected business workflows. Its finance automation case study confirms the deployment category but does not mean every invoice process requires an agent.
Verdict: Hybrid.
Human checkpoint: Payment approval, bank-detail changes and unresolved mismatches.
Best success measure: Correctly processed invoices without post-payment correction.
14. Expense-Management Agent
An expense agent can read receipts, extract amounts and vendors, categorize expenses and check them against the applicable policy.
If a hotel charge exceeds a limit, the agent might retrieve the relevant policy or ask the employee for missing context rather than automatically rejecting the submission. Anthropic uses a similar scenario in its explanation of agent planning, tool use and human escalation. It is an official illustration rather than a claimed customer deployment.
Verdict: Hybrid. Document processing and policy checks are structured; exception investigation may be agentic.
Human checkpoint: Policy exceptions, suspected fraud and reimbursement approval.
Best success measure: Accurate first-pass submissions and appropriate exception escalation.
15. Procurement-Support Agent
A procurement agent can collect requirements, search an approved supplier directory, identify missing due-diligence evidence and prepare a comparison for the responsible buyer.
The system may adapt its review according to the product or supplier risk. A software provider might require privacy and security evidence, while a physical supplier might require continuity, quality and delivery assessments.
The objective must not be reduced to obtaining the lowest price. Selection criteria may include resilience, legal terms, information security, sustainability and service quality.
Verdict: Hybrid. Evidence collection may be agentic, while supplier selection and contracting remain controlled decisions.
Evidence status: Illustrative application.
Human checkpoint: Supplier selection, risk acceptance and contract award.
Best success measure: Complete and accurate supplier-review packages.
16. Contract-Analysis Agent
A contract-analysis agent compares proposed language with an approved playbook, identifies unusual clauses and retrieves relevant fallback positions.
After execution, it may extract renewal dates, reporting duties and notice periods into a contract-management system. This is especially useful when obligations would otherwise remain buried in lengthy documents.
Every finding should cite the exact supporting clause. The system must distinguish extraction, comparison and legal interpretation.
Verdict: Hybrid. Clause comparison follows rules, while contextual investigation may require agentic reasoning.
Evidence status: Illustrative application.
Human checkpoint: Legal advice, negotiated positions and acceptance of material deviations.
Best success measure: Relevant issues found without excessive false positives.
17. Financial Reconciliation and Close Agent
A reconciliation agent retrieves approved records, compares balances and investigates differences across relevant systems.
When it encounters a discrepancy, it can choose the next source to inspect, identify timing differences and assemble supporting evidence for an accountant. It should not invent an explanation simply to close the task.
Financial controls still apply. An agent should not create and approve the same journal entry or bypass separation of duties.
Verdict: Hybrid. Matching is deterministic; investigation can be agentic.
Evidence status: Illustrative application.
Human checkpoint: Journal entries, materiality judgments and financial-statement approval.
Best success measure: Reconciliations accepted without subsequent adjustment.
People, Operations and Research
18. Employee-Onboarding Agent
An onboarding agent coordinates approved tasks across HR, IT, facilities and learning systems after a confirmed hiring event.
It can initiate role-based requests, assemble the employee’s schedule, provide approved policy information and monitor incomplete actions. Access permissions must come from validated role and identity data, not an agent’s guess about what the employee may need.
OpenAI’s enterprise research shows agent adoption expanding into recruiting and other non-engineering functions. This supports the broader enterprise pattern, although the onboarding workflow described here is not presented as a named customer deployment.
Verdict: Hybrid. Coordination may adapt, while identity and access provisioning should remain rule-governed.
Human checkpoint: Employment decisions, access privileges and exceptions to policy.
Best success measure: Correct completion of required onboarding tasks by the due date.
19. Supply-Chain Exception Agent
A supply-chain agent monitors shipments, inventory signals and supplier updates, then investigates events that fall outside expected conditions.
For a delayed consignment, it might inspect tracking data, evaluate available routes, calculate likely operational impact and notify the responsible planner. Updating an estimated arrival time may be low risk. Rerouting high-value or regulated goods requires approval.
TetriXX describes an agentic AI system designed to reduce transportation and logistics inefficiencies. Its Google Cloud logistics case study reports more than 99.99 percent availability for the agent. That is a company-specific, provider-published result rather than a general service benchmark.
Verdict: Agent.
Human checkpoint: Rerouting, additional expenditure and regulated shipments.
Best success measure: Correctly resolved exceptions without avoidable cost or delay.
20. Scientific Research Agent
A scientific research agent can break a question into subqueries, select relevant public and internal sources, execute analytical tools and revise its search as evidence emerges.
Genentech’s gRED Research Agent searches scientific literature and internal repositories, divides complex questions into multi-step workflows and produces cited findings. The published Genentech research-agent case study states that the system is expected to automate more than 43,000 hours of manual biomarker-validation work. This is a company estimate published by its cloud provider, not an independently verified general benchmark.
The agent supports scientists rather than replacing scientific judgment. Research conclusions must preserve source provenance, methodological limitations and uncertainty.
Verdict: Agent.
Human checkpoint: Scientific interpretation, study design and clinical application.
Best success measure: Relevant, correctly cited findings accepted by qualified researchers.
Which AI Agent Use Cases Should You Automate First?
The best first use case is not the one with the greatest theoretical autonomy. It is the workflow that produces measurable value while keeping errors detectable and recoverable.
The following decision matrix is editorial guidance rather than a scientifically validated scoring standard.
| Output verifiability | Consequence of error | Recommendation |
| High | Low | Strong first agent |
| High | High | Pilot with approval gates |
| Low | Low | Use as an assistant first |
| Low | High | Keep the process human-led |
A support-ticket routing agent is usually a better starting point than an autonomous pricing or hiring agent. Routing can be reviewed and reversed. Pricing and employment decisions can create lasting financial, legal and personal consequences.
Evaluate each candidate against these criteria:
| Criterion | Strong candidate | Weak candidate |
| Frequency | Repeats regularly | Rare or unpredictable |
| Process clarity | Goal and limits are documented | Experts disagree about the process |
| Data | Current and permissioned | Fragmented or unreliable |
| Verifiability | Output has clear evidence | Quality is highly subjective |
| Reversibility | Errors can be corrected | Actions create lasting harm |
| Exceptions | Recognizable and routable | Numerous unknown exceptions |
| Measurement | A baseline already exists | Success is undefined |
How to Implement an AI Agent Safely
1. Define One Job
Describe a specific outcome, the permitted tools and the point at which responsibility returns to a person.
“Resolve eligible delivery-status requests” is testable. “Manage customer service” is not.
2. Measure the Existing Process
Record the current completion time, error rate, rework, cost, escalation rate and user outcome. Without a baseline, the organization cannot determine whether the agent improves the process.
3. Restrict Data and Tools
Grant the minimum access needed for the task. Separate read permissions from write permissions and place sensitive actions behind technical approval controls.
4. Build a Representative Evaluation Set
Test routine cases, uncommon exceptions, incomplete instructions and adversarial inputs. The evaluation should examine whether the agent reaches the correct result, uses valid evidence and stops when uncertainty exceeds its authority.
5. Begin in Observation Mode
Allow the system to recommend actions without executing them. Compare its recommendations with actual outcomes and expert decisions before granting limited action rights.
6. Expand Authority Through Evidence
Begin with reversible actions. Increase autonomy only after evaluation and monitored operation demonstrate that the system remains within its intended boundaries.
Risks and Limitations of AI Agents
An incorrect chatbot answer may mislead a reader. An incorrect agent output can become an incorrect action.
The NIST Generative AI Profile explains that generative AI risks may arise during design, development, deployment, operation and decommissioning. It encourages organizations to incorporate trustworthiness considerations across the AI lifecycle.
| Risk | Operational effect | Control |
| Incorrect reasoning | Wrong action or recommendation | Validation and approval thresholds |
| Prompt injection | Untrusted content redirects the agent | Content isolation and limited tool access |
| Excessive permissions | Errors or attacks cause wider damage | Least privilege and scoped credentials |
| Data leakage | Restricted information reaches the wrong user | Source-level authorization |
| Automation bias | Reviewers accept weak outputs | Evidence display and meaningful review |
| Goal ambiguity | Agent optimizes the wrong outcome | Explicit objectives and stop rules |
| Error propagation | One agent misleads another | Independent validation between handoffs |
| Uncontrolled cost | Loops consume excessive resources | Time, action and spending limits |
| Weak accountability | No person owns the outcome | Named process and risk owners |
Prompt injection is particularly serious when agents process emails, documents and websites. Malicious instructions may be hidden inside apparently ordinary content. The more tools and permissions an agent has, the greater the potential consequence of a successful attack.
How to Measure AI Agent Performance
An agent should be evaluated according to completed work, not how fluent or confident it sounds.
A customer-service agent succeeds when it resolves eligible requests correctly, respects policy, escalates exceptions and records its actions. A coding agent succeeds when its changes pass independent review and testing, not when it produces the largest quantity of code.
Independent research on agent evaluation has also warned against focusing on accuracy while overlooking cost, robustness and reproducibility. The paper AI Agents That Matter argues for evaluating agents in ways that reflect real-world usefulness rather than benchmark performance alone.
| Dimension | Example measures |
| Task performance | Completion, accuracy and rework |
| Control performance | Correct escalation and policy compliance |
| Operational value | Cycle time, backlog and cost per task |
| Human impact | Review effort, satisfaction and override rate |
| Reliability | Failure consistency and recovery |
| Efficiency | Model, infrastructure and supervision cost |
The complete cost includes model usage, integrations, data preparation, security, evaluations, monitoring, human review and failure remediation.
Common AI Agent Implementation Mistakes
| Mistake | Why it fails | Better approach |
| Starting with a broad autonomous role | Scope and success are unclear | Define one bounded job |
| Making a deterministic workflow agentic | Adds cost and unpredictability | Keep fixed steps automated |
| Connecting every system immediately | Expands permissions and attack surface | Add tools gradually |
| Testing only routine cases | Hides failures until production | Include exceptions and hostile inputs |
| Measuring generated output | Rewards activity instead of value | Measure completed, accepted work |
| Removing review too early | Allows errors to become actions | Expand autonomy through evidence |
| Ignoring source permissions | Exposes restricted information | Enforce access at the source |
| Treating escalation as failure | Encourages unsafe guessing | Reward appropriate escalation |
Conclusion
The most useful AI agent examples are not unrestricted systems attempting to run entire departments. They are focused agents that complete recognizable work through approved tools, respond to feedback and return uncertain or consequential decisions to accountable people.
Customer service, software engineering, knowledge retrieval and document processing are attractive starting points because their results can be evaluated. Finance, HR, procurement, cybersecurity, logistics and scientific research can also benefit, but they require stronger permissions, evidence trails and approval controls.
Start with one recurring workflow that has reliable data, measurable outcomes and reversible actions. Establish the baseline, test difficult cases, deploy the agent initially in observation mode and increase its authority only when operational evidence supports the change.